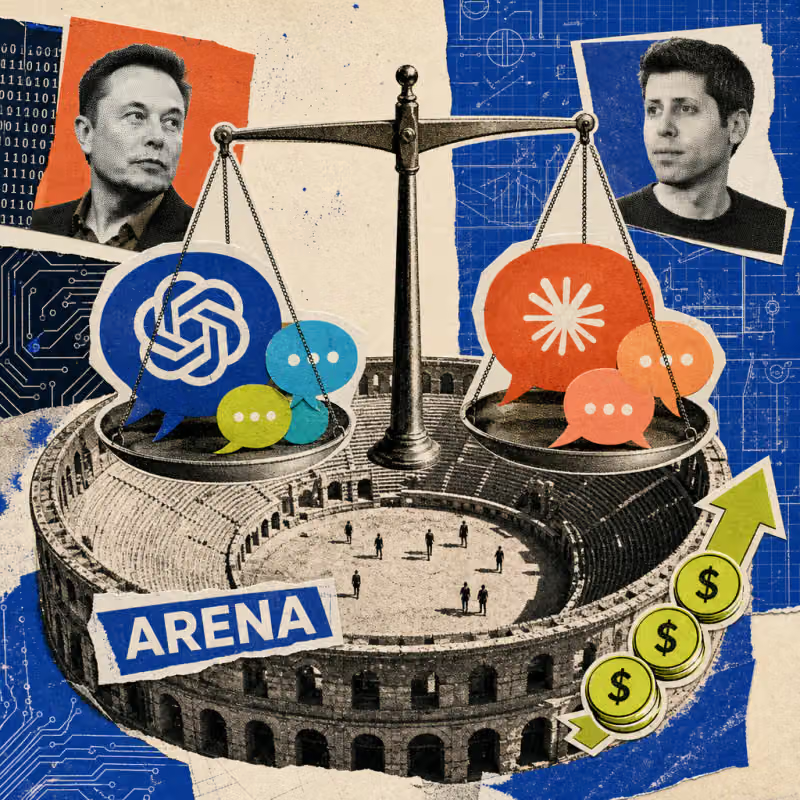
The AI evaluation platform Arena has completed a Series B funding round of 200 million dollars and is now valued at 3.1 billion dollars. This is almost double the amount from the previous round in January 2026, led by Lightspeed Venture Partners and Khosla Ventures.
Valuation rises by 1.4 billion dollars in ten months
According to TechCrunch, the new round included participants such as Salesforce Ventures, Dell Technologies Capital, Andreessen Horowitz, and Felicis.
In January 2026, Arena, then still known as LMArena, raised 150 million dollars at a valuation of 1.7 billion dollars. The valuation has since increased by 1.4 billion dollars in ten months.
The company was founded in 2023 as a research project at the University of California, Berkeley, according to Bloomberg, letting users anonymously compare responses from various AI models.
In September 2025, the paid product AI Evaluations followed for model labs and companies, providing performance analytics based on community ratings.
Annual revenue grew, according to Arena, from 30 million dollars in January to over 100 million dollars in June 2026. The company does not publish a fixed price list for AI Evaluations; the free comparison portal, however, remains accessible via the browser without registration, including for users in Germany and the EU.
According to its own figures, the portal draws double-digit millions of visitors each month.
Alignment index checks AI agents for deception and overreach
Alongside the funding round, Arena introduced a new alignment index that measures how trustworthy AI agents act in practice. Three criteria are evaluated: unauthorized actions a model takes without being asked, false attribution of statements or facts to the wrong source, and feigned task completion, where an agent reports an unfinished task as done.
For companies deploying AI agents in customer service or software development, the index is meant to offer an additional, comparable metric once vendor benchmarks alone no longer suffice.
According to TechCrunch, several OpenAI models lead the preliminary ranking, with Anthropic's Claude Opus 5.5 in sixth place and Claude Fable in ninth. Arena argues that the value of one-off benchmark tests fades once models recognize they are being tested.
The ranking is based, according to further reporting, on more than 90,000 real agent sessions across 27 models, scored by Arena's own AI model acting as judge rather than by human reviewers. This figure is independently unverified; Arena itself has not yet confirmed it in a publication of its own.
Market for neutral AI evaluation grows with the agent boom
Arena thus joins the ongoing tracker for AI funding and valuations, where investors have recently focused increasingly on infrastructure around AI models rather than the models themselves.
Providers of training data and sales automation such as Snorkel AI and Clay have also tripled or doubled their valuations in recent months.
Demand for independent evaluation is also growing because companies, according to a report on OpenAI, Google, and Anthropic, can barely keep pace with the speed of new model releases and increasingly lean on third-party rankings instead of vendor claims.
An alignment index like Arena's promises a more neutral basis for comparison – provided methodology and underlying data are disclosed.
Competitors such as Scale AI or Surge AI offer similar evaluation services, but mostly on behalf of individual clients rather than through an open, crowdsourced ranking. Arena's roots as an academic comparison portal are meant to help it position itself as a neutral party, even though it is now commercially funded by the same labs it rates.
What will matter is whether the alignment index establishes itself as an independent benchmark, even as Arena works commercially with the same labs whose models it rates. It also remains open whether Arena will lay out the methodology behind the ranking – such as the exact session count and the judging model's role – in a publication of its own.